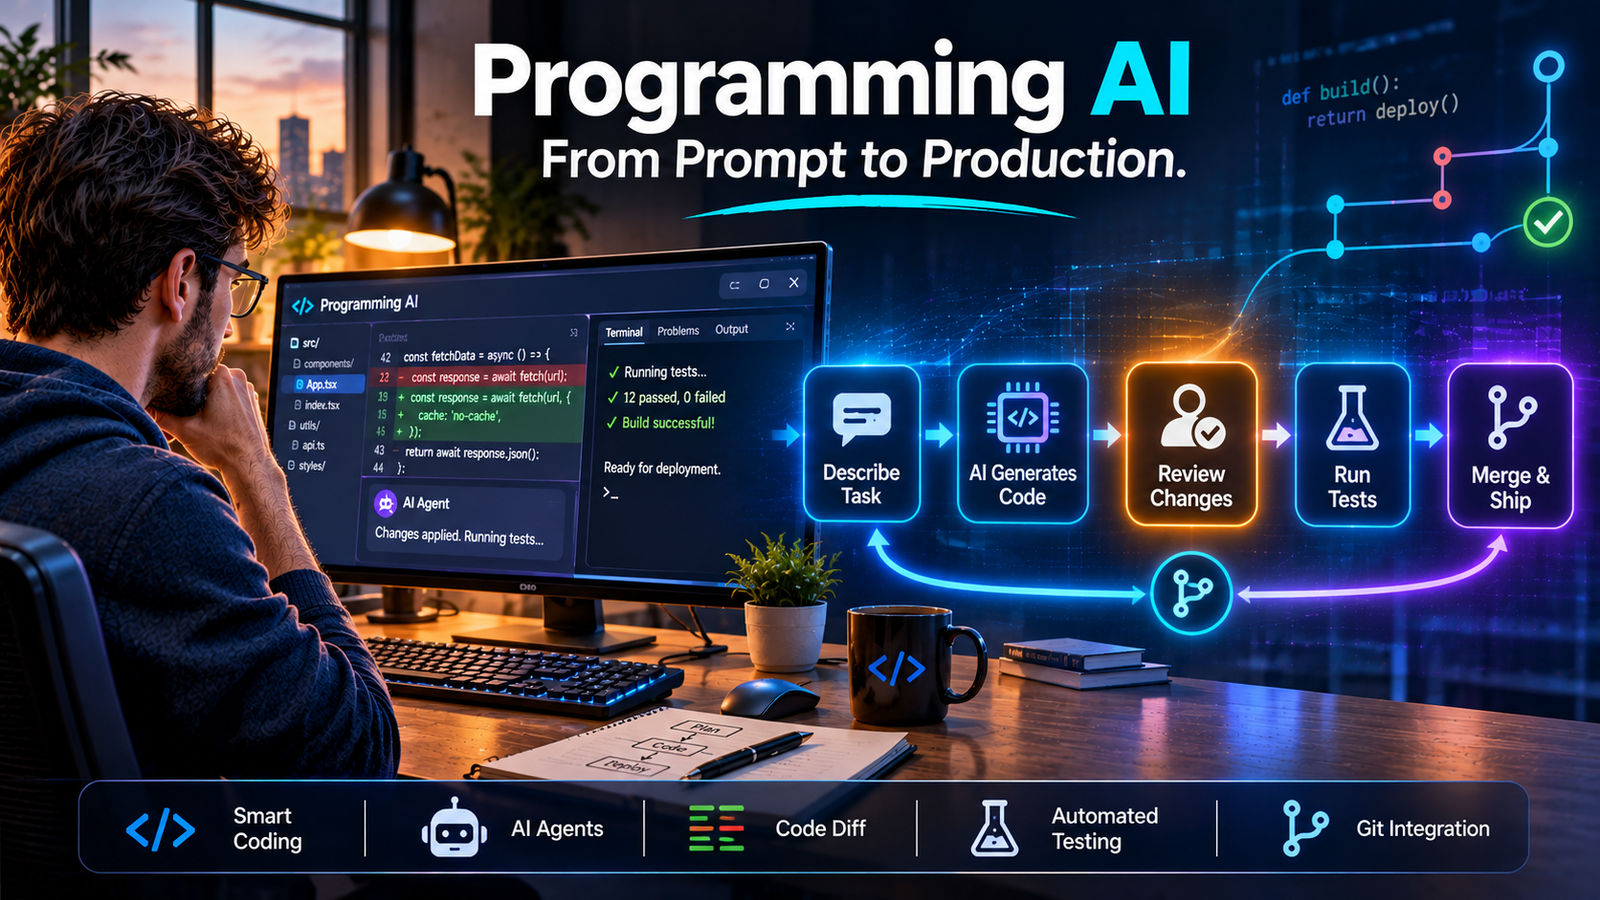
Programming AI refers to tools that use large language models to write, complete, refactor, and debug code inside a developer’s workflow. The category spans editor-integrated assistants like GitHub Copilot, agent-first IDEs like Cursor, and terminal-based agents like Claude Code, each with distinct strengths and costs.
At a Glance
- Three main categories: Inline completion (Copilot), agentic IDEs (Cursor), and terminal agents (Claude Code, Codex CLI)
- Adoption is mainstream: 84% of developers use or plan to use AI coding tools, with over half using them daily
- Review is the bottleneck: AI-generated code waits 4.6 times longer for review than human-written code, according to LinearB data
- Pricing varies widely: Copilot starts at $10/month, Cursor at $20/month, Claude Code at $17/month via Claude Pro
- Editor lock-in matters: Cursor requires switching to its VS Code fork; Copilot works across most major editors
- Data residency drives choice: Teams that cannot send code to third-party APIs need self-hosted options like Aider or Continue.dev
What Is Programming AI?
Programming AI is not a single product. It is a category of tools built on large language models that assist with software development tasks.
The category has matured rapidly. Stack Overflow’s 2025 survey found that 84% of respondents already use or plan to use AI in their development process, and 50.6% of professional developers report daily use . These are not experimental side projects. They are daily workflow tools.
The tools differ in where they run and how much autonomy they take. Some complete lines as you type. Others accept a task description and work independently for minutes at a time. Understanding these distinctions matters more than comparing feature lists.
The Three Categories of Programming AI
Inline Completion Assistants
These tools sit inside your existing editor and suggest code as you type. GitHub Copilot is the dominant example.
The workflow is low-friction. You keep your editor, your extensions, and your habits. Copilot suggests completions, and you accept or reject them. The tool works across VS Code, JetBrains, Visual Studio, Neovim, Xcode, and Eclipse .
The limitation is scope. Inline completion excels at boilerplate and predictable patterns. It struggles with multi-file changes that require understanding how different parts of a codebase interact.
Agent-First IDEs
Cursor is the defining product in this category. It is a fork of VS Code with AI built into the editor’s core rather than bolted on as an extension.
Cursor’s key feature is Composer, an agent that handles multi-file refactors, feature scaffolding, and dependency updates in a single flow . You describe what you want, and the agent produces a diff you review at the end.
The tradeoff is commitment. Cursor requires your whole team to switch editors. For teams with engineers on JetBrains, Neovim, or other environments, this creates a two-tier setup that Copilot avoids .
Terminal-Based Agents
Claude Code and OpenAI’s Codex CLI run from the command line. They operate on repositories directly, making commits and running tests without requiring an IDE.
Claude Code is the terminal-first option that works with any editor and integrates with Git . It is stronger for large-scale refactoring and backend work than for real-time completion. Codex CLI offers similar capabilities with GPT models, including a sandbox mode for local command execution .
The appeal is flexibility and data control. Claude Code can run against self-hosted models, which matters for teams with strict data residency requirements. Codex CLI is open source under Apache 2.0 .
Key Tools Compared
Pricing: What You Actually Pay
Programming AI pricing has shifted from flat subscriptions to credit-based models. That change matters for budgeting.
GitHub Copilot now meters chat, agents, and code review in AI Credits. Completions remain unlimited on paid plans. Pro is $10 per month with $15 in credits; Pro+ is $39 with premium model access . The free tier offers 2,000 completions and 50 chat requests monthly.
Cursor separates usage into its own models and third-party models. Pro is $20 per month with $20 of API-rate usage included. Ultra is $200 per month with $400 in usage . Third-party models like Claude and GPT are billed at API list price on top of the subscription.
Claude Code is included with Claude Pro at $17 per month billed annually, or $20 monthly. Max plans start at $100 per month . Heavy usage can hit session limits.
Codex CLI is included with ChatGPT Plus at $20 per month. API-key usage bills per token at rates like $5 input and $30 output per million tokens for the highest tier .
The practical advice is to model your actual usage before choosing a tier. A team of ten developers doing daily agent work can exceed entry-level credits quickly.
Where Programming AI Falls Short
Review Bottlenecks
AI generates code faster than teams can review it. LinearB tracked 8.1 million pull requests and found that AI-generated code waits 4.6 times longer for review than human-written code .
The cause is volume. A developer who generates a 400-line diff in minutes creates a review burden that the team’s process was not designed to handle. Reviewers face longer diffs without the context that a human pair programmer would have shared during the session.
Teams that handle this well adopt specific habits. They cap AI-assisted pull requests at around 200 lines. They require context in PR descriptions. Some run dedicated async review blocks separate from development time .
The Editor Lock-In Problem
Cursor’s advantages come at the cost of editor flexibility. Teams with Neovim users, JetBrains users, and VS Code users cannot deploy Cursor without forcing a migration.
Copilot is the only major tool that works across all these environments . For organizations with heterogeneous toolchains, this matters more than agent sophistication.
Data Residency and Privacy
Neither Cursor nor Copilot works for organizations that prohibit sending code to third-party servers. Aider with a self-hosted model and Continue.dev with Ollama are the options that cover this case .
Both require infrastructure setup and model selection. For teams in financial services, healthcare, or jurisdictions with strict data localization laws, this operational overhead is unavoidable.
Model Quality Varies by Language
AI coding tools perform best on widely used languages with large amounts of public training data, like Python and JavaScript. Support for niche or newer languages is less consistent . Teams working in specialized domains should test tools on their actual codebase before committing.
Real-World Examples: What Works and What Doesn’t
Multi-File Refactoring
Claude Code handles changes touching 10 or more files well, especially when the task requires reading more than it writes. It can run tests between edits .
Cursor Composer is better for 3 to 10 file changes where fast visual feedback matters. Its diff preview and atomic accept flow is smoother for medium-size work .
Past 30 files, neither tool performs quickly. Large migrations need explicit chunking.
Debugging
Cursor wins on debugging because the IDE has the debugger, breakpoints, terminal, and test runner in one place. The agent can iterate against a failing test without context switching .
The leverage technique is consistent across tools: get a failing test first, then let the agent iterate. Vague prompts like “make this work” produce hallucinated fixes.
Test Generation
Copilot and Cursor win on inline test generation from a highlighted function. Claude Code wins for bulk test generation across many files or property-based tests .
The universal failure mode is AI tests that assert what the implementation does rather than what it should do. Test-first workflows reduce this risk.
Who Should Use What
Choose GitHub Copilot if:
- Your team uses mixed editors
- You want the lowest entry price ($10/month)
- Your workflow is GitHub-centric
- You need enterprise controls and SSO
Choose Cursor if:
- Your team is willing to standardize on one editor
- You do multi-file agent work weekly
- You want the strongest tab completion available
- Budget allows $20 to $200 per month per developer
Choose Claude Code if:
- You work in the terminal
- You need large-scale refactoring across many files
- You want editor flexibility
- You have a Claude Pro subscription
Choose Aider or Continue.dev if:
- Data residency rules prohibit third-party APIs
- You want to self-host models
- Open-source tooling is a requirement
Many experienced developers use more than one tool. A common combination is Cursor for daily editor work plus Claude Code for cross-codebase refactors .
Common Mistakes When Adopting Programming AI
Letting AI generate oversized pull requests. Cap AI-assisted PRs at 200 lines to keep review cycles fast .
Skipping review context. Require PR descriptions that state what the AI was asked to do, which model was used, and which files were in context. Reviewers need this to evaluate changes effectively.
Assuming accuracy. AI suggestions can contain subtle bugs and security issues. Review and test them like any other code .
Ignoring the credit model. Copilot’s move to AI Credits means heavy agent usage can exceed budget. Model your actual usage before choosing a tier .
Forcing editor migrations. If half your team uses JetBrains, Cursor creates a two-tier setup. Copilot avoids this problem.
Overlooking data residency. If compliance prohibits sending code to OpenAI or Anthropic servers, test Aider or Continue.dev before committing to a cloud-dependent tool.
Frequently Asked Questions
What is the best programming AI tool for beginners?
GitHub Copilot’s free tier offers 2,000 completions and 50 chat requests monthly with no credit card. It works inside familiar editors and provides a low-risk way to test AI assistance. Cursor also has a free Hobby tier with limited agent requests.
Can programming AI replace human developers?
No. AI tools accelerate specific tasks like boilerplate generation, test writing, and refactoring. They do not replace judgment about architecture, security, or business logic. Human code review remains essential.
Is AI-generated code safe to use in production?
It can be, with proper review. AI suggestions can contain bugs and security vulnerabilities. Treat AI output like code from a junior developer: review it, test it, and do not merge without human oversight.
Why does AI-generated code take longer to review?
Volume. AI produces large diffs quickly, creating review queues that outpace team capacity. Teams that cap PR size and require context in descriptions report faster reviews .
Which programming AI works with my existing editor?
GitHub Copilot works with VS Code, JetBrains, Visual Studio, Neovim, Xcode, and Eclipse. Cursor requires switching to its VS Code fork. Claude Code and Codex CLI work from the terminal and are editor-agnostic.
Conclusion
Programming AI has moved from novelty to daily workflow for most professional developers. The tools are genuinely useful for specific tasks: completing boilerplate, generating tests, and handling multi-file refactors when scoped correctly.
The choice between tools matters less than the workflow around them. Review capacity is the real constraint. Teams that cap PR size, require context, and maintain human oversight get value from AI assistance. Teams that let agents generate unlimited code without adjusting review processes create bottlenecks.
Programming AI suits developers willing to adapt their workflow and review habits. It may not suit teams with strict editor standardization, data residency prohibitions that rule out cloud APIs, or workflows where review bandwidth cannot scale.
Before committing, test one tool on a real task from your backlog. Measure how long the AI-generated code takes to review and fix. Compare that against your current baseline. The tool that fits is the one whose output your team can actually ship.